Causal Inference with Video Features as Treatments
Kentaro Nakamura, Adam Breuer, Michael H. Crespin, Bryce J. Dietrich, Kosuke Imai
*Preprint PDF*
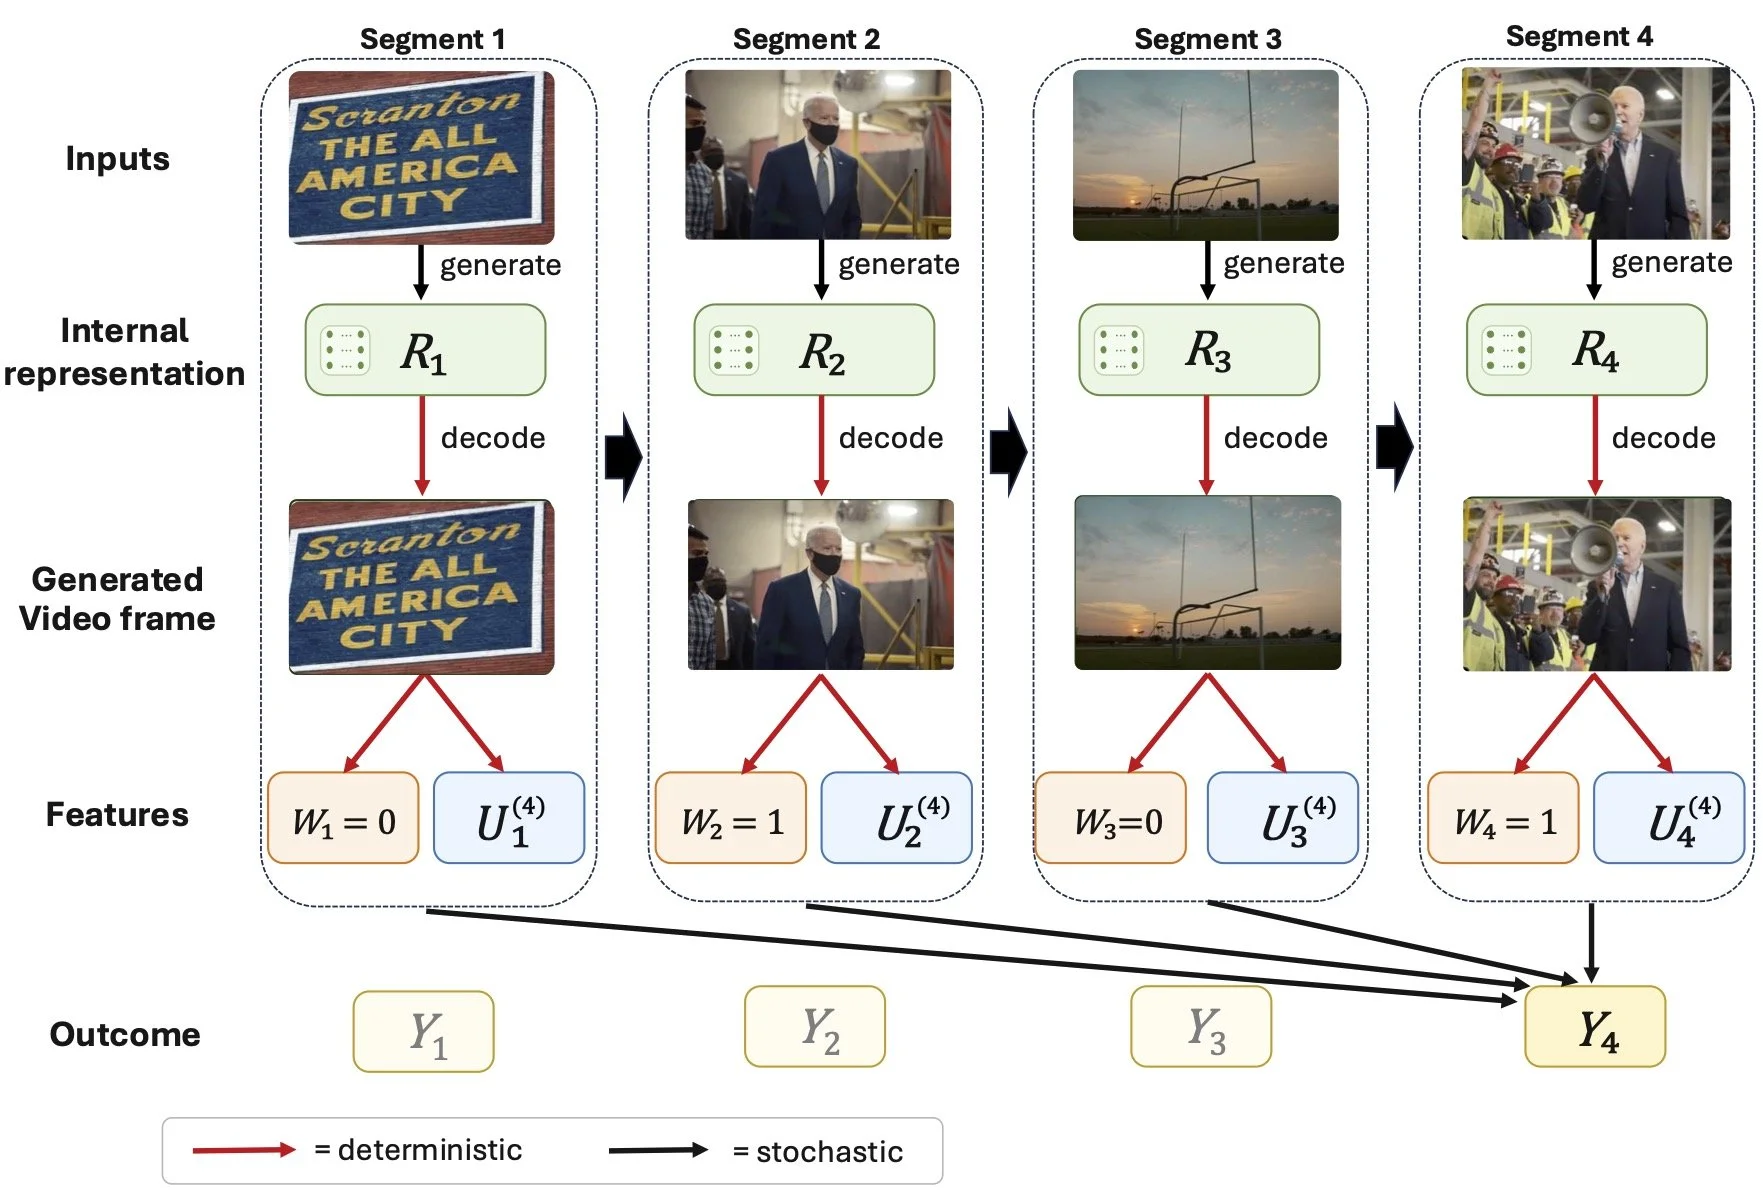
Summary: We develop the first statistical methodology for causal inference with video features as treatments. With our methodology, researchers can for the first time ask which visual features, appearing at which points in a video, influence audience responses.
Displacement Geometry Captures Platonic Shared Reality Across Models and Modalities
Chenming Shang, Yujin Tang, Jun Jie Ou Yang, Ruize Xu, Adam Breuer (co-PI), Nikhil Singh (co-PI)
Published in: NeurIPS’26 (forthcoming)
*Preprint PDF forthcoming*
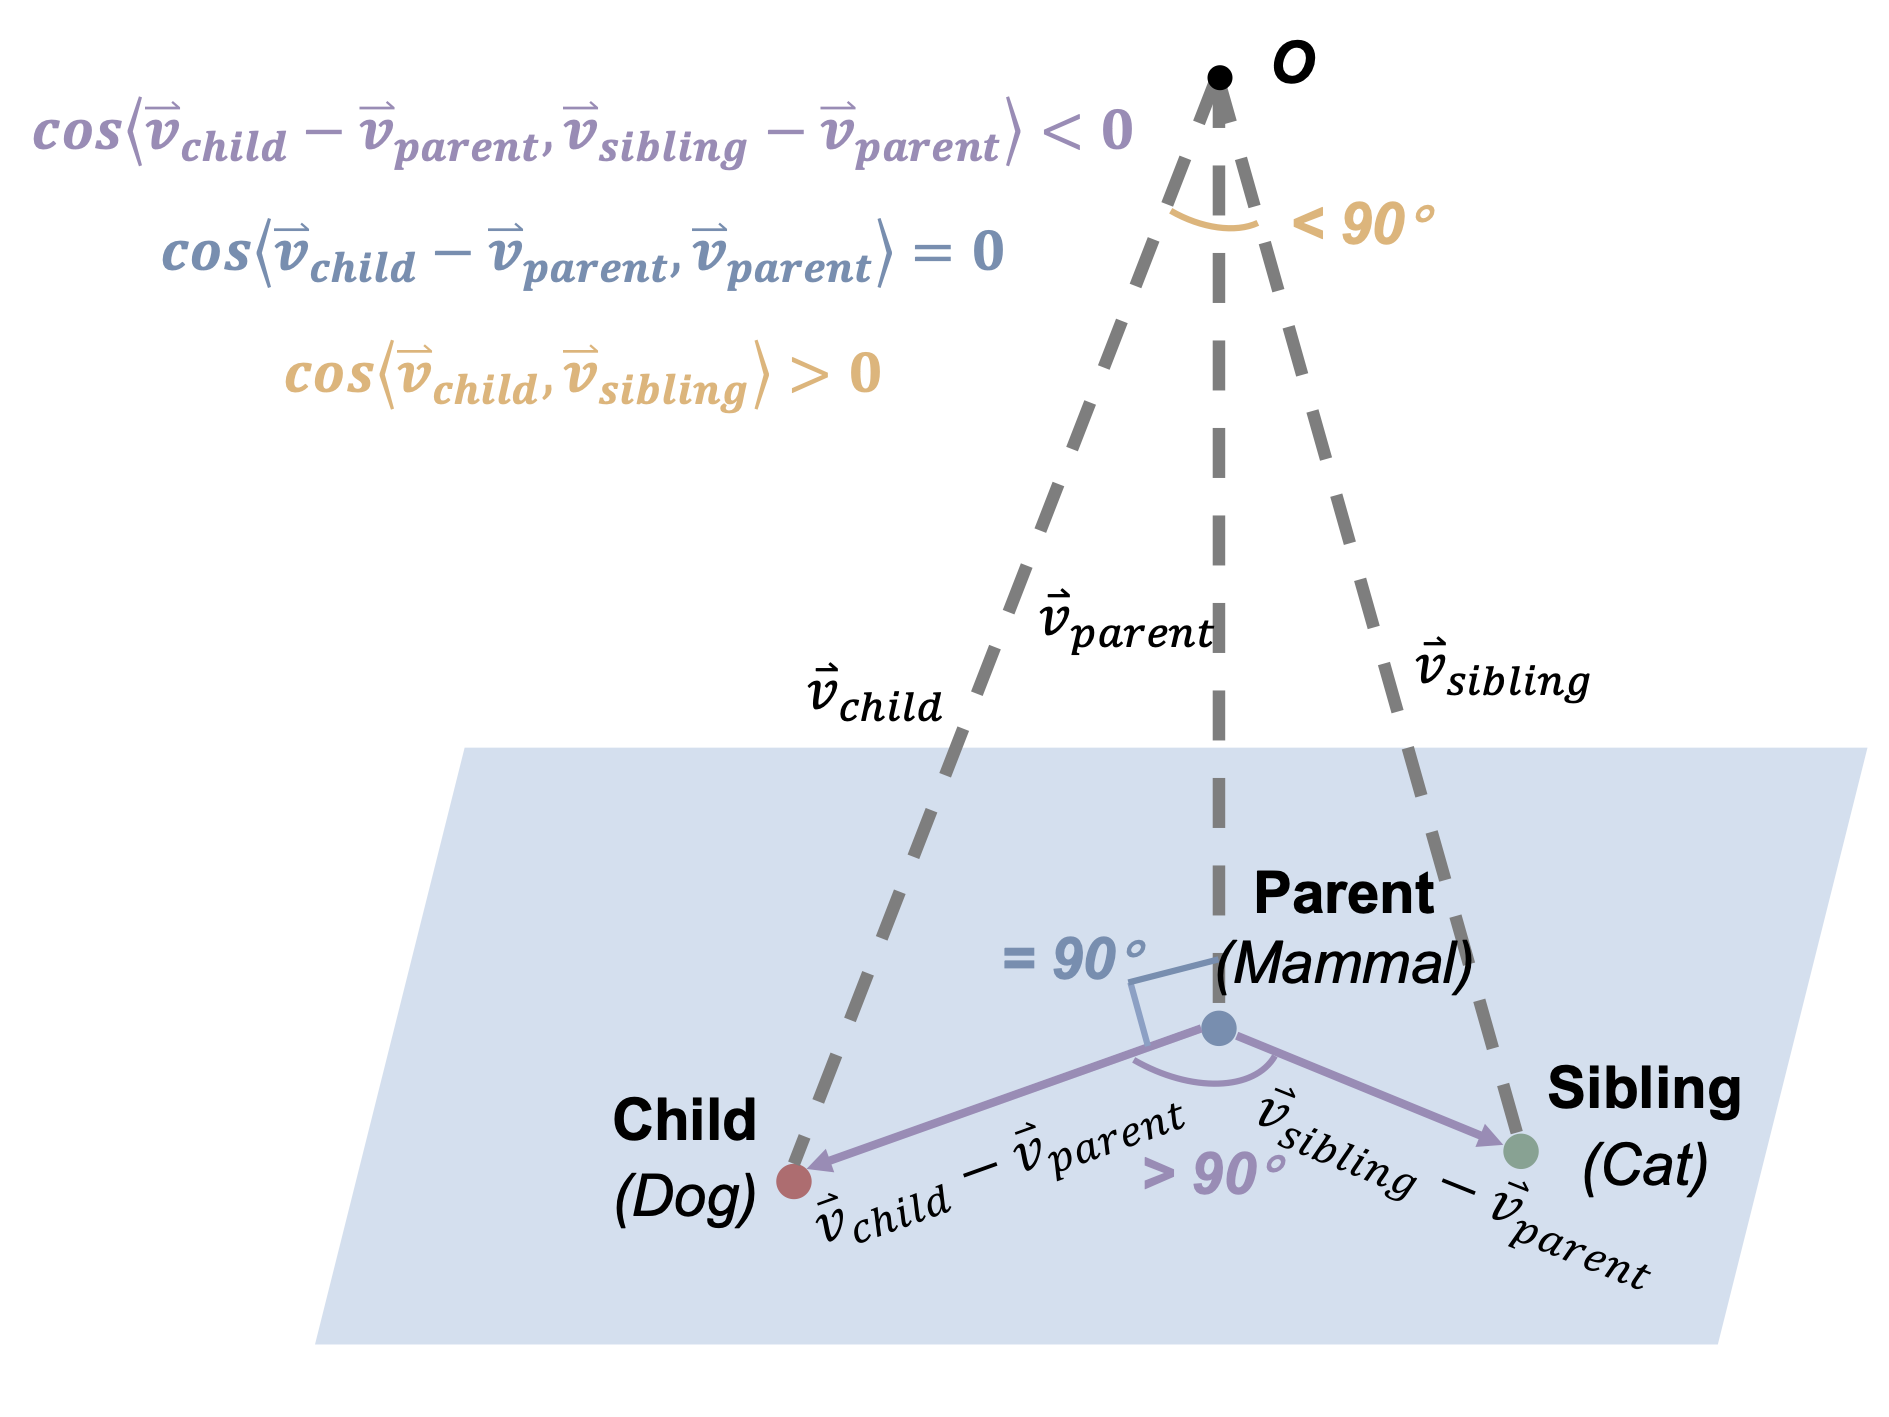
Summary: The Platonic Representation Hypothesis (PRH) claims that independently trained models converge on a shared statistical model of reality, yet recent work finds only weak pointwise similarity between models. In this paper, we resolve this disagreement by showing that that what models share is not the location of samples in representation space, but the directions (displacement vectors) between them. Under a single orthogonal alignment limited to just rotation and reflection, these displacement vectors are substantially preserved across 44 independently trained vision and language encoders spanning modalities and asymmetric capability pairs. We trace this geometry to concept-level structure: within a model, parent concepts are orthogonal to their child variation vectors; across models, concept displacements are parallel. A major implication is that capabilities can be imported from one model to another using a single cached forward pass through the source.
FU-AUTHOR: Attribution-Based Compensation Is Incentive-Incompatible for LLMs
Matthew Keating, Rasmus Torp, Adam Breuer
Published in: NeurIPS’26 ATTRIB (forthcoming)
*Preprint PDF forthcoming*
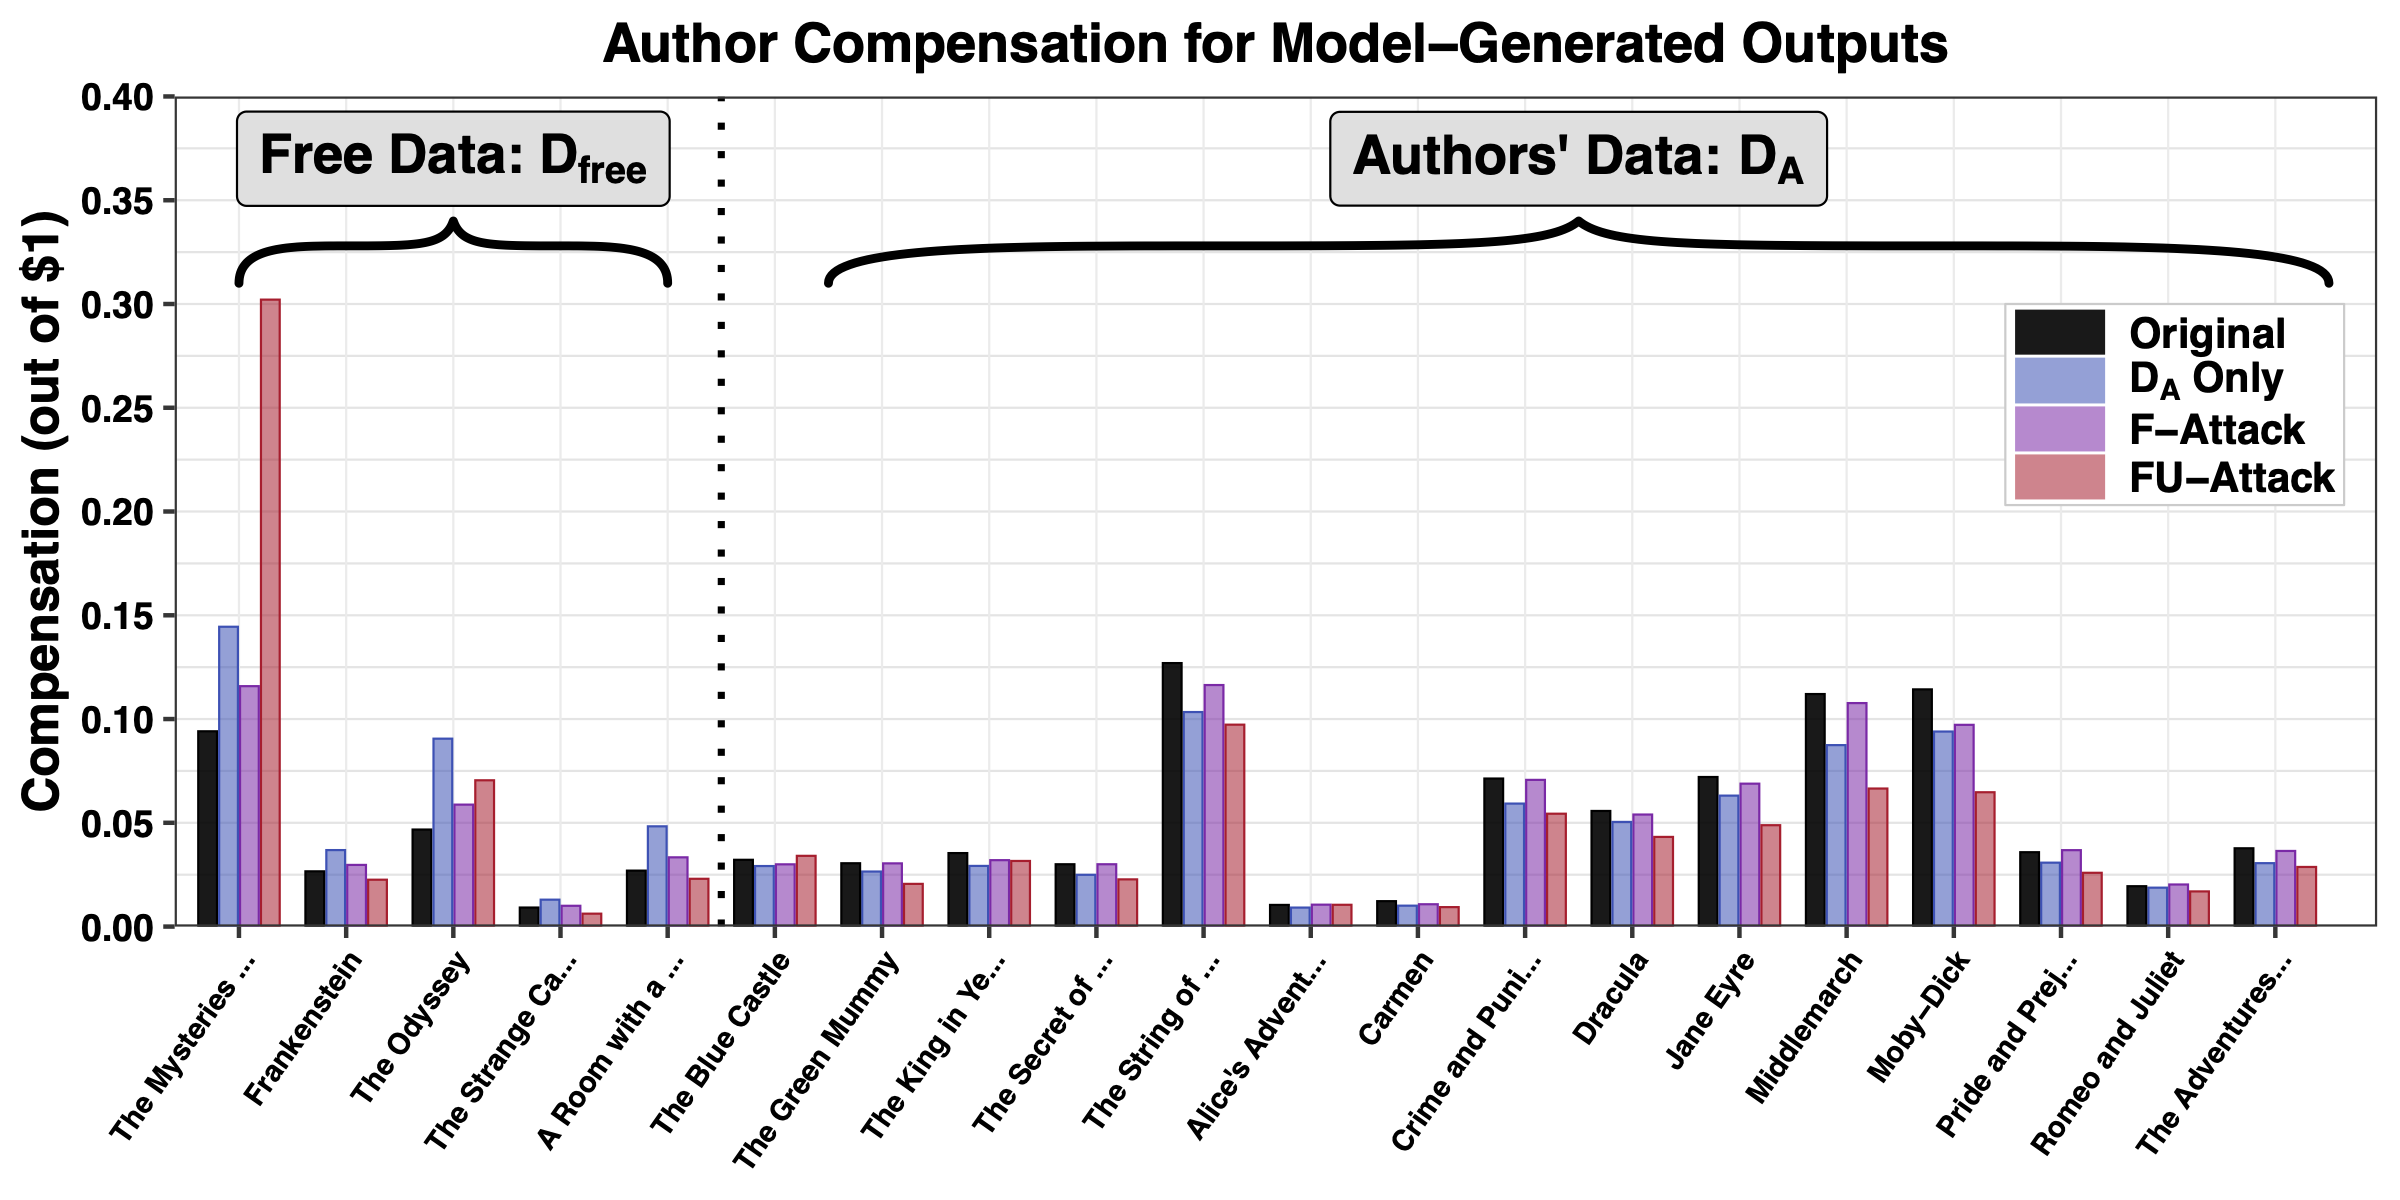
Summary: We show that attribution-based compensation mechanisms proposed to pay authors for their work can perversely reward AI companies for paying them less. AI companies can retain value from authors' works while shifting attribution, and therefore compensation, toward copyright-free data of their choosing. In one illustrative attack, a model generates Star Wars-like text that TRAK attributes to Shakespeare. We show that AI companies can accomplish this without subterfuge, corruption, or alteration of authors' data. Our `attacks' on fair compensation require neither knowledge of the exact attribution mechanism nor queries to it. Nor do they require an AI company to break the proposed attribution rules. Instead, we show that proposed attribution mechanisms are incentive-incompatible, even under unrealistically idealistic assumptions.
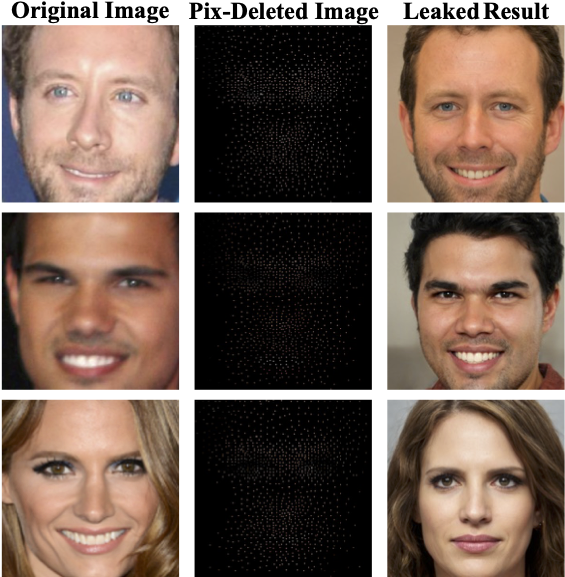
Reducing information dependency does not cause training data privacy. Adversarially non-robust features do
Rasmus Torp, Shailen Smith, Adam Breuer
Published in: ICLR’26
*Download PDF*
Summary: Prevailing theory holds that state-of-the-art models leak sensitive private information, such as individuals’ faces or medical data, because models memorize training data and/or learn training data information dependencies. We begin by presenting a variety of surprising results that overturn this prevailing view. Specifically, we show that models can catastrophically leak private data even when training data is 98% censored (i.e. absent memorization), violating the assumptions and protections promised by recent information-theoretic privacy bounds. Instead, our OpenAI-funded research shows that privacy leakage is caused by so-called non-robust features, revealing a never-before-observed link between state-of-the-art privacy defenses and adversarial examples. We introduce a novel algorithm, Anti-Adversarial Training (AT-AT), which leverages this connection to obtain superior privacy at higher accuracy than the state of the art. Our results revise the prevailing understanding of training data exposure and reveal a new privacy–robustness tradeoff.
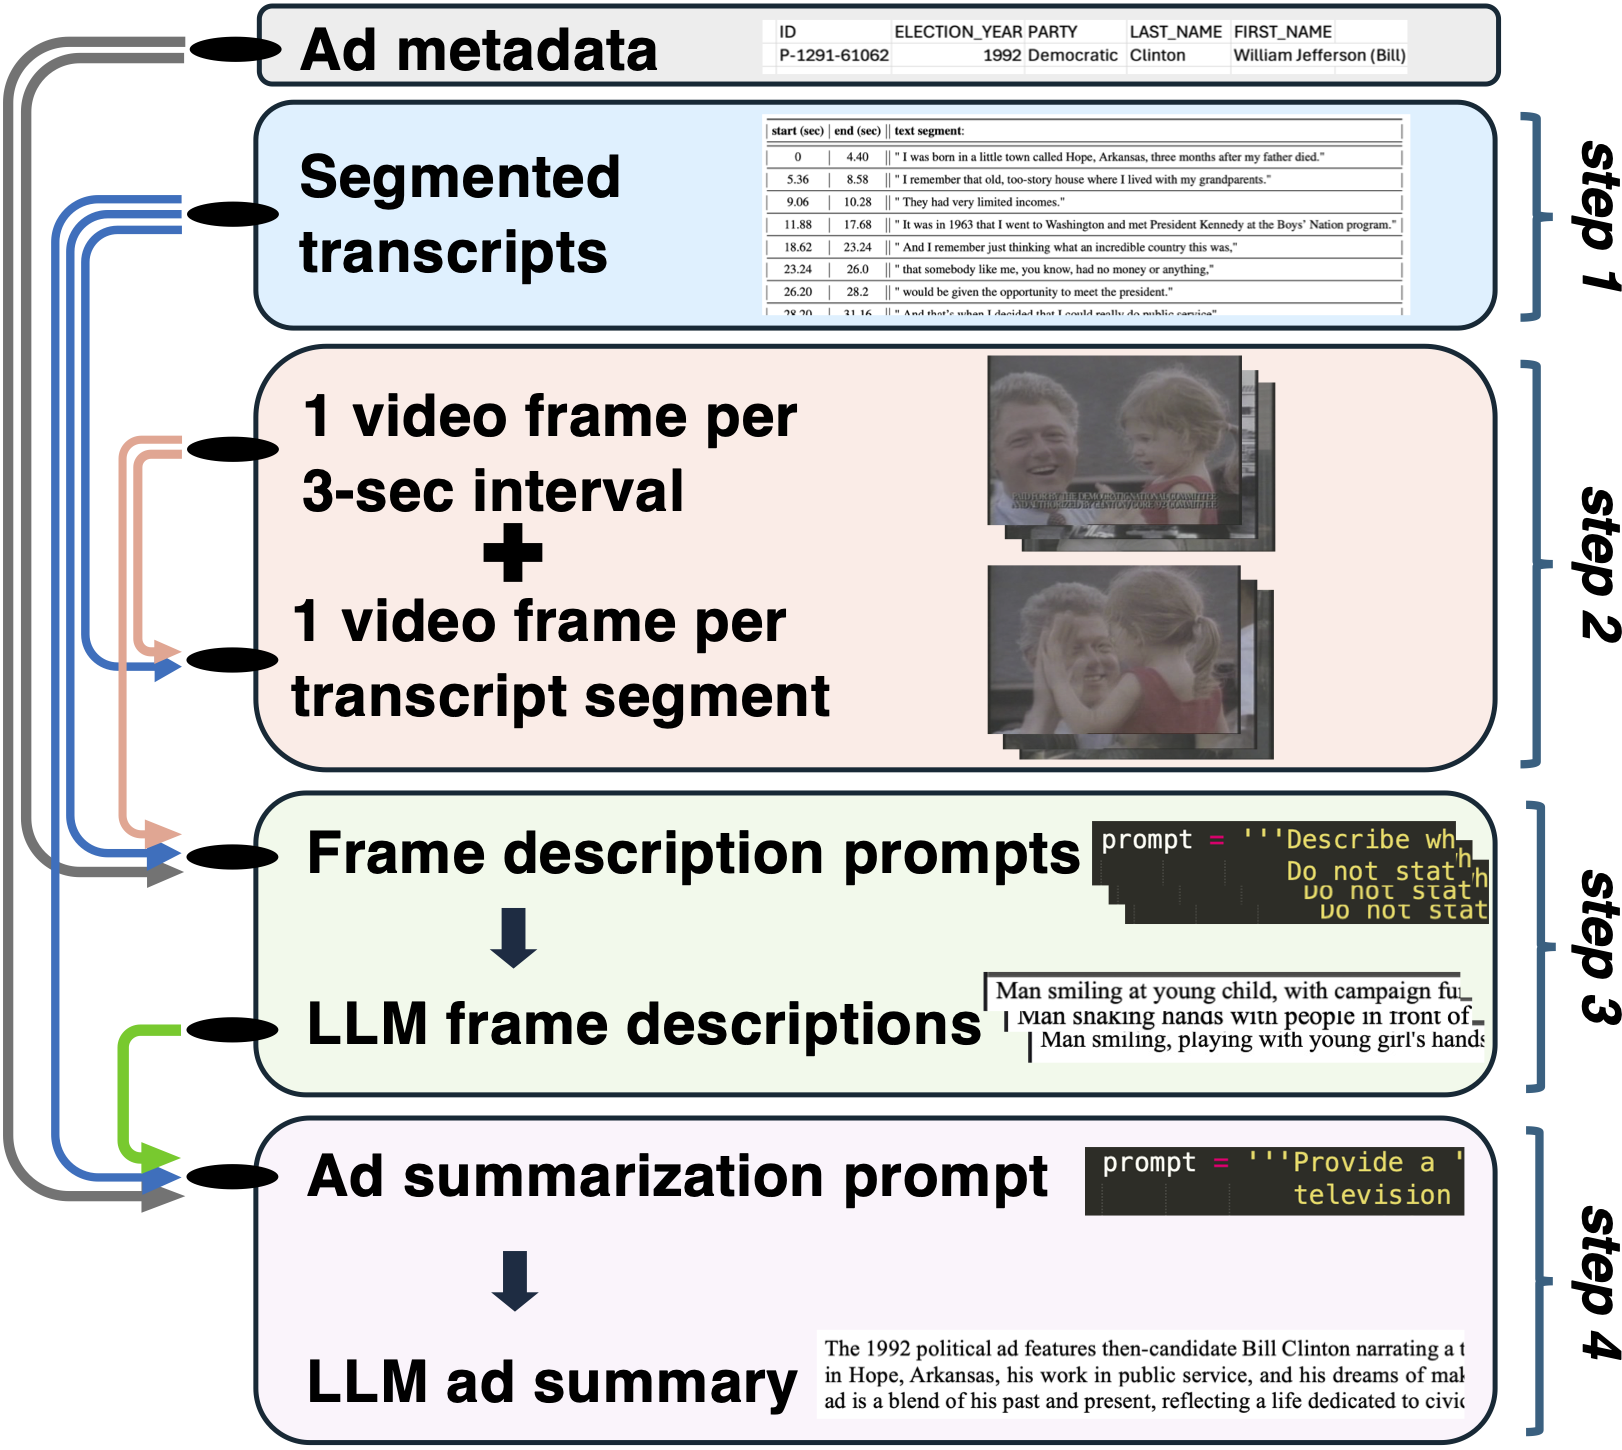
Using AI to Summarize US Presidential Campaign TV Advertisement Videos, 1952-2012
Adam Breuer, Bryce J. Dietrich, Michael H. Crespin, Matthew Butler, J.A. Pyrse, Kosuke Imai
Published in: Nature: Scientific Data (2025)
*Download PDF*
Summary: This paper introduces the largest and most comprehensive dataset of US presidential campaign television advertisements, available in digital format. To facilitate a variety of research, we design a large-scale parallelized, AI-based analysis pipeline that automates the laborious process of preparing, transcribing, and summarizing videos, and we conduct extensive human evaluations to show that these transcripts and summaries match the quality of manually generated alternatives. We illustrate the value of this data by including an application that tracks the genesis and evolution of current focal issue areas over seven decades of presidential elections. Our analysis pipeline and codebase also show how to use LLM-based tools to obtain high-quality summaries for other video datasets.

Toward Interpretable LDA Topic Models with Strong Guarantees in Logarithmic Parallel Time
Adam Breuer
Published in: ICML'25
*Download PDF *
Summary: This paper presents the first combinatorial algorithms that provably solve LDA topic models with near-optimal posterior probability in logarithmic parallel computation time—exponentially faster than any known LDA algorithm. Our approach resolves several longstanding open problems in topic modeling by providing formal interpretability guarantees and the first provable guarantees for downstream causal inference applications, which are the primary use case for topic models in the social sciences. Empirically, our algorithms consistently produce topic models of higher semantic quality than state-of-the-art LDA algorithms, neural topic models, and LLM-based topic models.

Improving Robustness to Model Inversion Attacks via Sparse Coding Architectures
Sayanton Dibbo, Adam Breuer, Juston Moore, and Michael Teti
Published in: ECCV'24
*Download PDF*
Summary: Model inversion attacks permit adversaries to reconstruct a neural network's private training data just by repeatedly querying the network and inspecting its outputs. In this work, we develop a novel network architecture that leverages sparse-coding layers to obtain superior robustness to this class of attacks. Our techniques connect three decades of computer science research on sparse coding in other contexts to state-of-the-art privacy vulnerabilities. We show how it can be used to obtain equal or higher classification accuracy while outperforming the defense metrics obtained by standard benchmarks by factors of 1.1 to 18.3.

Preemptive Detection of Fake Accounts on Social Networks via Multi-Class Preferential Attachment Classifiers
Adam Breuer, Nazanin Khosravani (Facebook Research), Michael Tingley (Facebook Research), and Bradford Cottel (Facebook Research)
Published in: KDD'23, Research Track, Selected for Oral Presentation & headlined KDD Misinformation focus area.
*Download PDF*
Summary: We leverage Facebook data to design a new algorithm called PreAttacK. PreAttacK has the first provable guarantees for detecting fake accounts on social networks that apply to new users, and that do not require strong network homophily assumptions. PreAttacK is also the only algorithm with provable guarantees that obtains state-of-the-art performance on new users on the global Facebook network, where it converges to AUC=0.9 after new users send + receive a total of just 20 not-yet-answered friend requests.

Friend or Faux: Graph-Based Early Detection of Fake Accounts on Social Networks
Adam Breuer, Roee Eilat (Facebook Research), Udi Weinsberg (Facebook Research)
Published in: Oral Presentation in the 29th ACM The Web Conference 2020 (WWW’20)
*Download PDF*
Summary: Fake accounts are the main source of fake news on social networks, and Facebook disabled over 6 billion fake accounts in 2019. We present the first social network-based algorithm capable of reliably detecting fake accounts (AUC>0.9) among new social network users before they have made many connections. We implement this algorithm at scale at Facebook and show that it outperforms state-of-the-art algorithms.

Memes, narratives and the emergent US–China security dilemma
Adam Breuer and Alastair Iain Johnston
Published in: Cambridge Review of International Affairs
*Download PDF*
Summary: The US–China rivalry is associated with a prominent meme that describes China as ‘challenging the international rules-based order’ (RBO). We theorize that tracking the speed and spread of such memes provides both a useful indicator of security dilemma dynamics and a basis on which to theorize the process by which security narratives emerge in international relations. We assemble a database of the full texts of virtually every online English-language article published about China, and we use plagiarism analysis to reconstruct the network of inter-media and government-media influences responsible for the spread of the RBO meme over time. We provide preliminary evidence that the RBO meme may be crowding out other, less malign narratives about China’s rise.

The FAST Algorithm for Submodular Maximization
Adam Breuer, Eric Balkanski, and Yaron Singer
Published in: ICML 2020
*Download PDF* *Link to talk available July 18* Code & Replication
Summary: Across machine learning, social network analysis, and algorithms, many fundamental objectives we care to optimize are submodular, such as influence, innovation diffusion, clustering, mutual information, feature selection, and data summarization. Recently, there has been a great deal of research on parallel algorithms for submodular maximization whose theoretical runtime on an idealized parallel machine is exponentially faster than algorithms used over the past 40 years. However, it is computationally infeasible to use these algorithms in practice even on small data sets. In this paper, we a new parallel algorithm called Fast Adaptive Sequencing Technique (FAST) for maximizing a monotone submodular function under a cardinality constraint k. The design principles behind the FAST algorithm are a significant departure from recent theoretically fast algorithms. These principles yield theoretic guarantees that are competitive with recent theoretically fast algorithms, but superior practical performance. Specifically, we show that FAST is orders of magnitude faster than any known algorithm for submodular maximization, including hyper-optimized parallel versions of state-of-the-art serial algorithms, by running experiments on large data sets.

Non-monotone Submodular Maximization in Exponentially Fewer Iterations
Eric Balkanski, Adam Breuer, and Yaron Singer
Published in: NeurIPS 2018
*Download PDF*
Summary: We introduce an algorithm that achieves an approximation to constrained non-monotone submodular maximization exponentially faster than any previously studied algorithm. We show applications to several domains in machine learning and optimization.

Identifying Peer Effects on Participation in Collective Action: Evidence from a set of natural experiments in cell phone movement & communication metadata
Adam Breuer
(Awarded NSF SES Grant)

Algorithmic discovery of efficient envy-free division protocols for games of complete and incomplete information
Adam Breuer